File fields
Extend Files with your own fields, so a file carries the metadata your process actually needs.
Files are a data object like any other, which means you can extend them. Labels are good for loose, reusable tagging, but they are a poor place to record that a statement came from a particular custodian, or which reporting period it covers. Those are fields.
A field you add to Files shows up wherever files appear: as a column in a file view, in the file's own properties, in filters and sorts, and as a series on a canvas.
The fields Spark ships with are a different matter. Name, Original Name, Labels, Created By and the rest of the standard set are the schema the application itself reads and writes, so they are locked.
Open the field settings
- In the left sidebar, open the Settings tab.
- Under Features, select File.
The Files fields page splits into two sections:
- Custom, the fields you added. Open by default, with a count and a New button.
- Standard fields, the ones Spark provides. Folded away and read-only, with the note Provided by Spark. They can be displayed and filtered, but not renamed or archived.
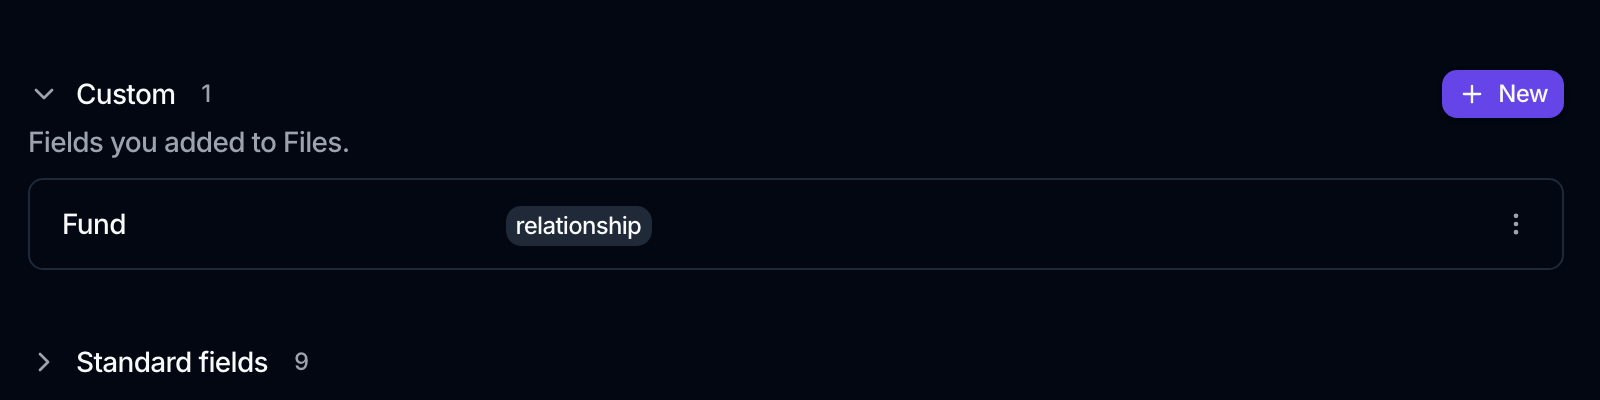
Standard fields cannot be renamed, retyped or archived, and that is enforced by the API rather than only hidden in the interface. A file's Name will always mean what the rest of Spark expects it to mean.
Add a field
- In the Custom section, click New.
- Give the field a Name and pick its Type.
- Configure the type if it needs it, for example the linked object on a relationship, or the values on a select.
- Click Create.
The types available here are narrower than on your own data objects: String, Number, Boolean, Date, Select, Multi-select, User and Relationship. There is no Formula type, and no File type, since the record already is one. For what each type stores, see Attribute types.
A Relationship is the useful one here. Point a field at your Funds or Counterparties object and every file can say which record it belongs to, which is what turns a folder of documents into something you can filter and report on.
A new field lands in the default file view straight away, so it is available in the column picker, filters and sorts without any further step.
Edit, format, archive and restore
Each custom field has a ⋮ menu:
- Edit changes its name and description. The type is locked once the field exists, the same rule as anywhere else in Spark.
- Display configuration formats a number field: decimals, separators, a prefix or a suffix. See Format how a number displays.
- Archive hides the field everywhere it appears. The confirmation says it plainly: The field is hidden everywhere it appears. Its values are kept and come back if you restore it.
- Restore brings an archived field back. Archived fields carry an Archived badge and sort below the live ones.
Where a custom field appears
Once a field exists, it is available on every surface that reads files:
| Surface | How it shows up |
|---|---|
| The Files table | As a column you can add per view from Display, and drag into position |
| Filter and Sort | As an attribute to filter or sort on, like any standard field |
| Canvas table, chart and KPI widgets | As a column or a series, since Files are a selectable data source |
| Workflows | As a field a file-triggered workflow can read, and a Save Record step can write |
Each saved view picks its own columns, so the field being available does not mean every view suddenly shows it. See Organize files.
Filling a field automatically
A field is only as useful as it is filled in, and nobody wants to tag a hundred uploads by hand. A file-triggered workflow runs when a file arrives and can write its fields: read the filename or the contents, work out which fund or period it belongs to, and set the field on the file itself.